
Case study
LLM Provider Benchmarking
In plain English
Scores extraction models on your own documents before you lock a provider.
Routing decisions come from your field accuracy, not a public leaderboard.
Who it is for
- Platform owners about to lock a provider.
- ML leads who need numbers on their cards, not a public leaderboard.
Problem
Reputation is a bad way to pick a model. Defaulting to GPT-class overpays. Defaulting to the cheapest model hides field loss.
The client needed hierarchical accuracy on their own claims (overall, per card, per field, plus page-class) before moving traffic.
Solution
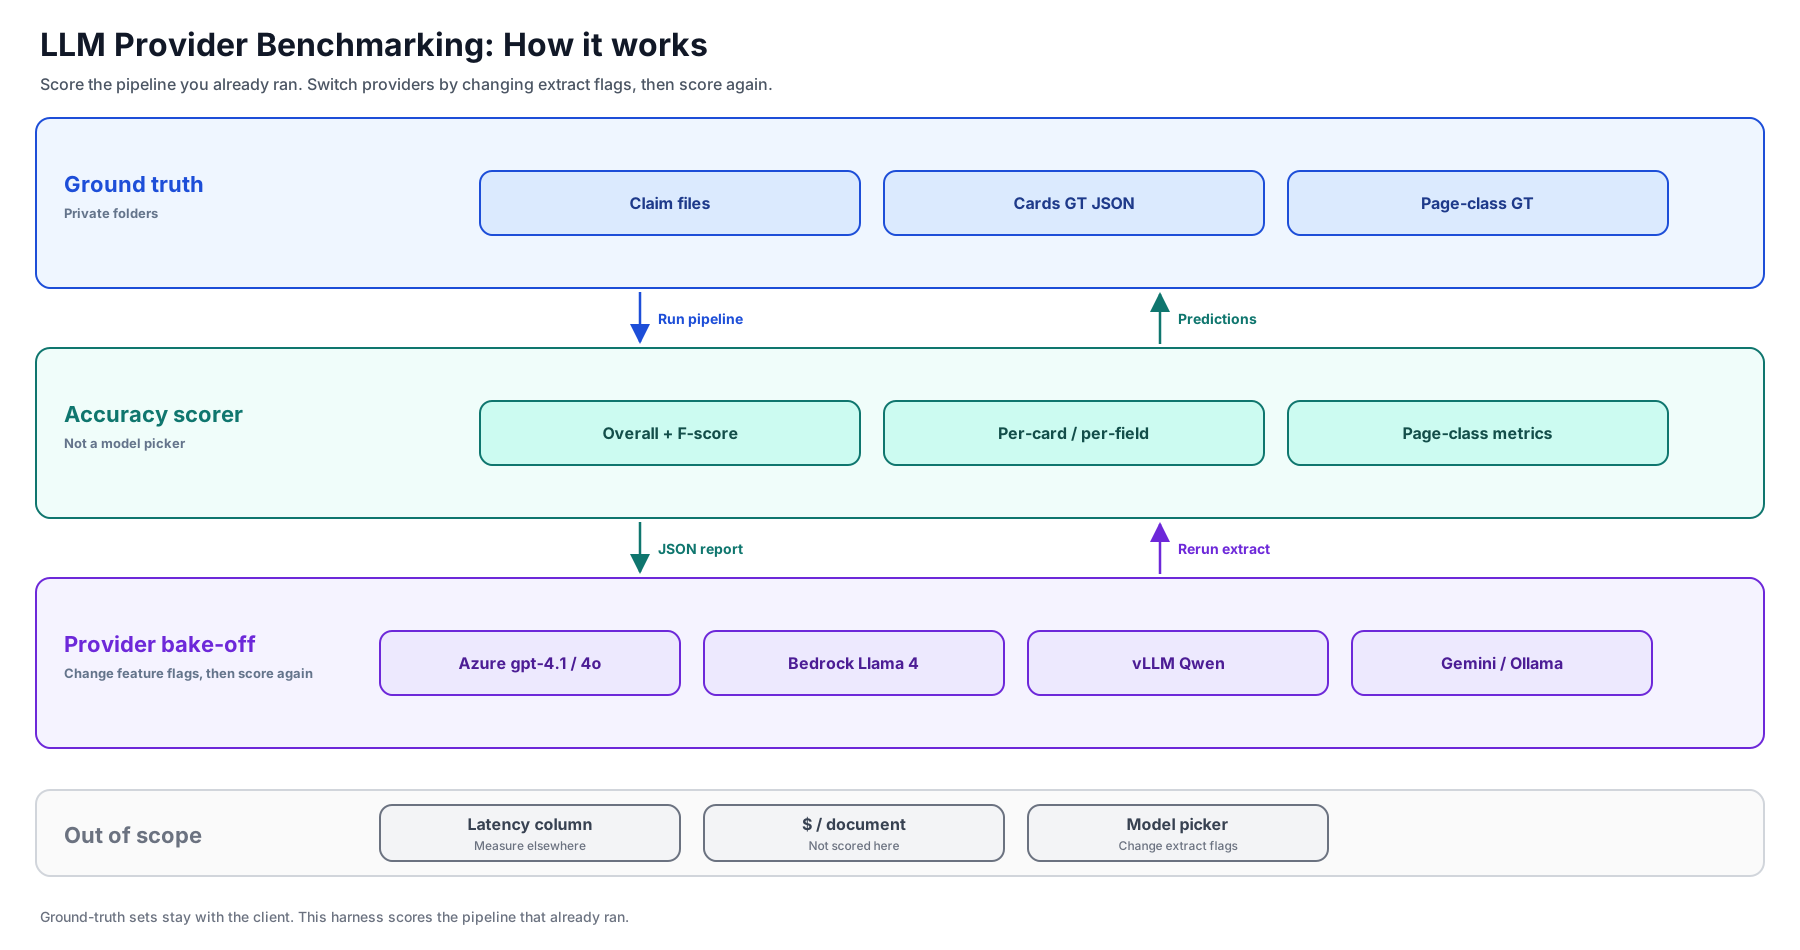
The harness scores whatever the extraction pipeline already wrote for a test folder. It does not pick a model. Operators upload ground truth, wait for claims, and get JSON: overall accuracy and F-score, per-card and per-field scores, and page-classifier metrics.
A provider bake-off means changing extract feature flags (Azure, Bedrock, vLLM Qwen, Gemini, Ollama), re-running, and scoring again. Latency and cost-per-document are measured outside this harness.
Outcomes
Rerunnable cards and page-class scores against private ground truth.
Routing policy is then configured on the extract workers from evidence, not a public leaderboard.
How it works
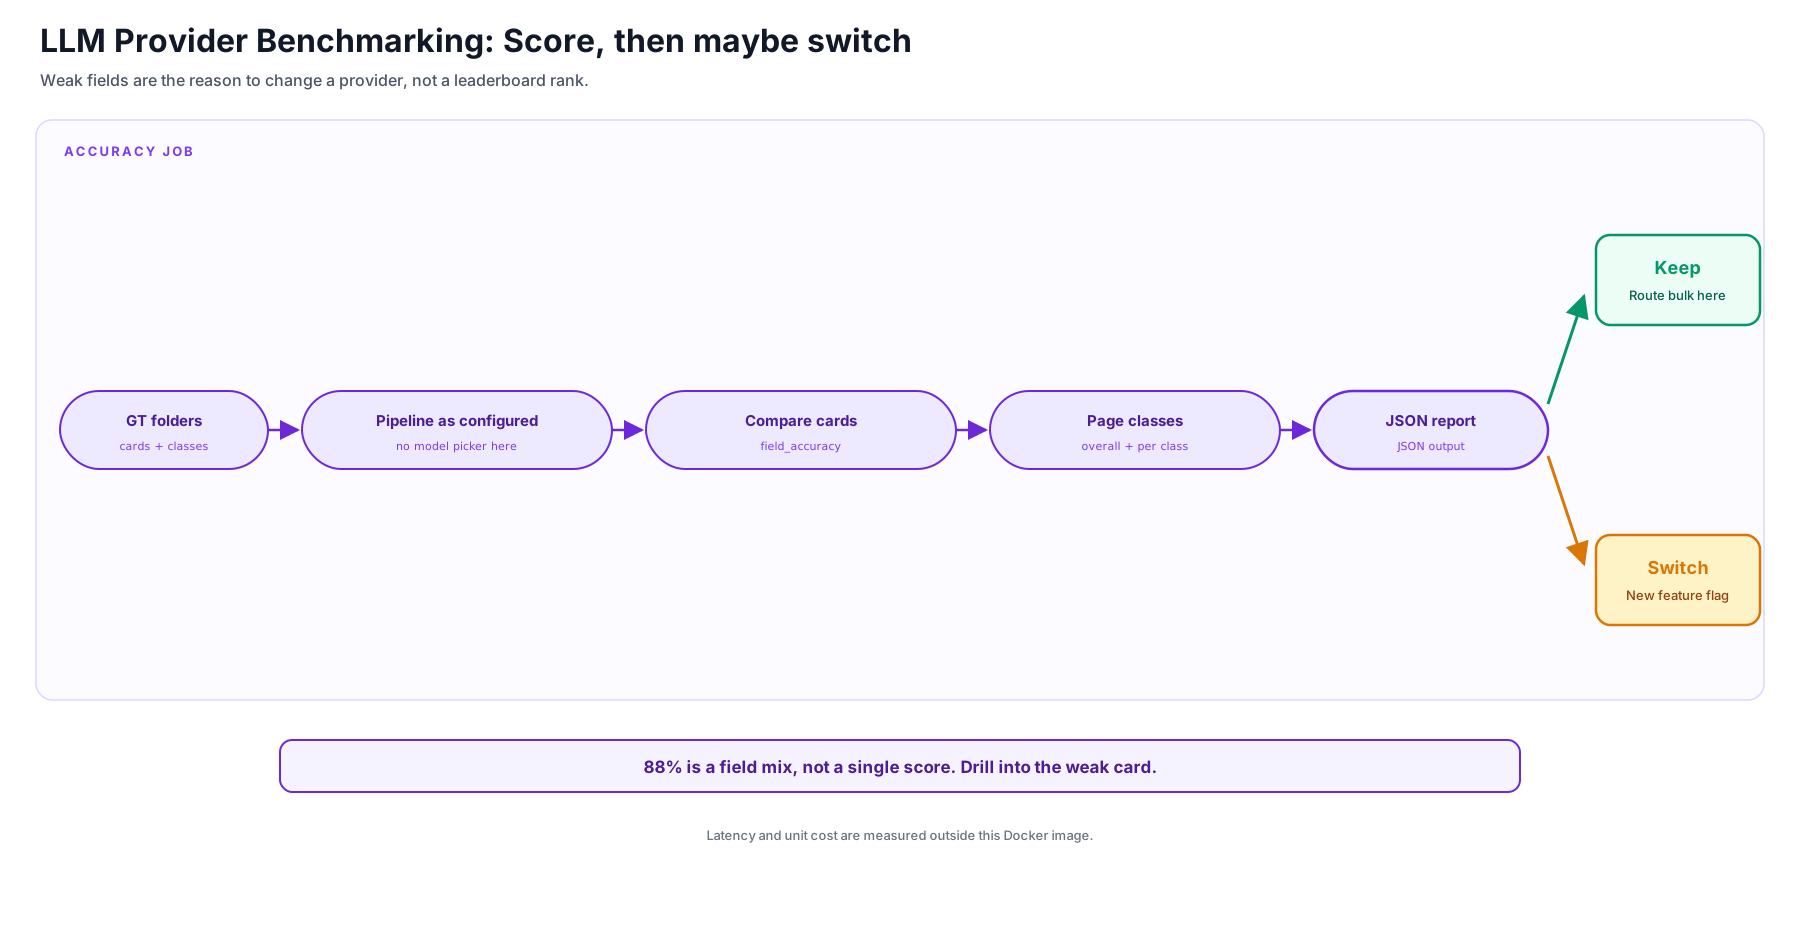
Score, then maybe switch
What we built
Accuracy API
Same ground truth, pipeline as configured
No model dropdown. Score the run you already made.
Hierarchical scores
Overall accuracy and F-score, per card, per field, plus page-class metrics.
Manual bake-off
Change extract flags, re-run, score again. Azure, Bedrock Llama, vLLM Qwen, Gemini, Ollama.
Feeds routing
Weak fields are why you switch a provider, not a leaderboard rank.
How it works
There is no user-facing model picker. Operators submit eval jobs; JSON lands as a report. Ground-truth sets stay with the client.
This harness scores the pipeline that already ran. Latency and unit cost are measured elsewhere.
Integrations
Extraction pipeline
Provider switches live as extract feature flags, then this scorer compares output to ground truth.
Azure, Bedrock, Gemini
Hosted extract candidates, scored after a rerun.
vLLM Qwen and Ollama
Self-hosted extract candidates on the same ground truth.
Have a similar challenge?
Start a project