
Case study
Local LLM Deployment & Serving
In plain English
Runs extraction models on owned GPUs so sensitive pages do not have to leave the building.
Cost per document dropped from about $0.35 to about $0.10.
Who it is for
- Teams with medical or insurance pages that should not ride a public API.
- Platform owners paying frontier rates for bulk extract.
Problem
Bulk extraction depended on hosted APIs: per-token cost, rate limits, and pages leaving the building. Hugging Face generate loops wasted VRAM.
Cloud queue metrics lag by minutes, too slow to scale extract workers against a real backlog.
Solution
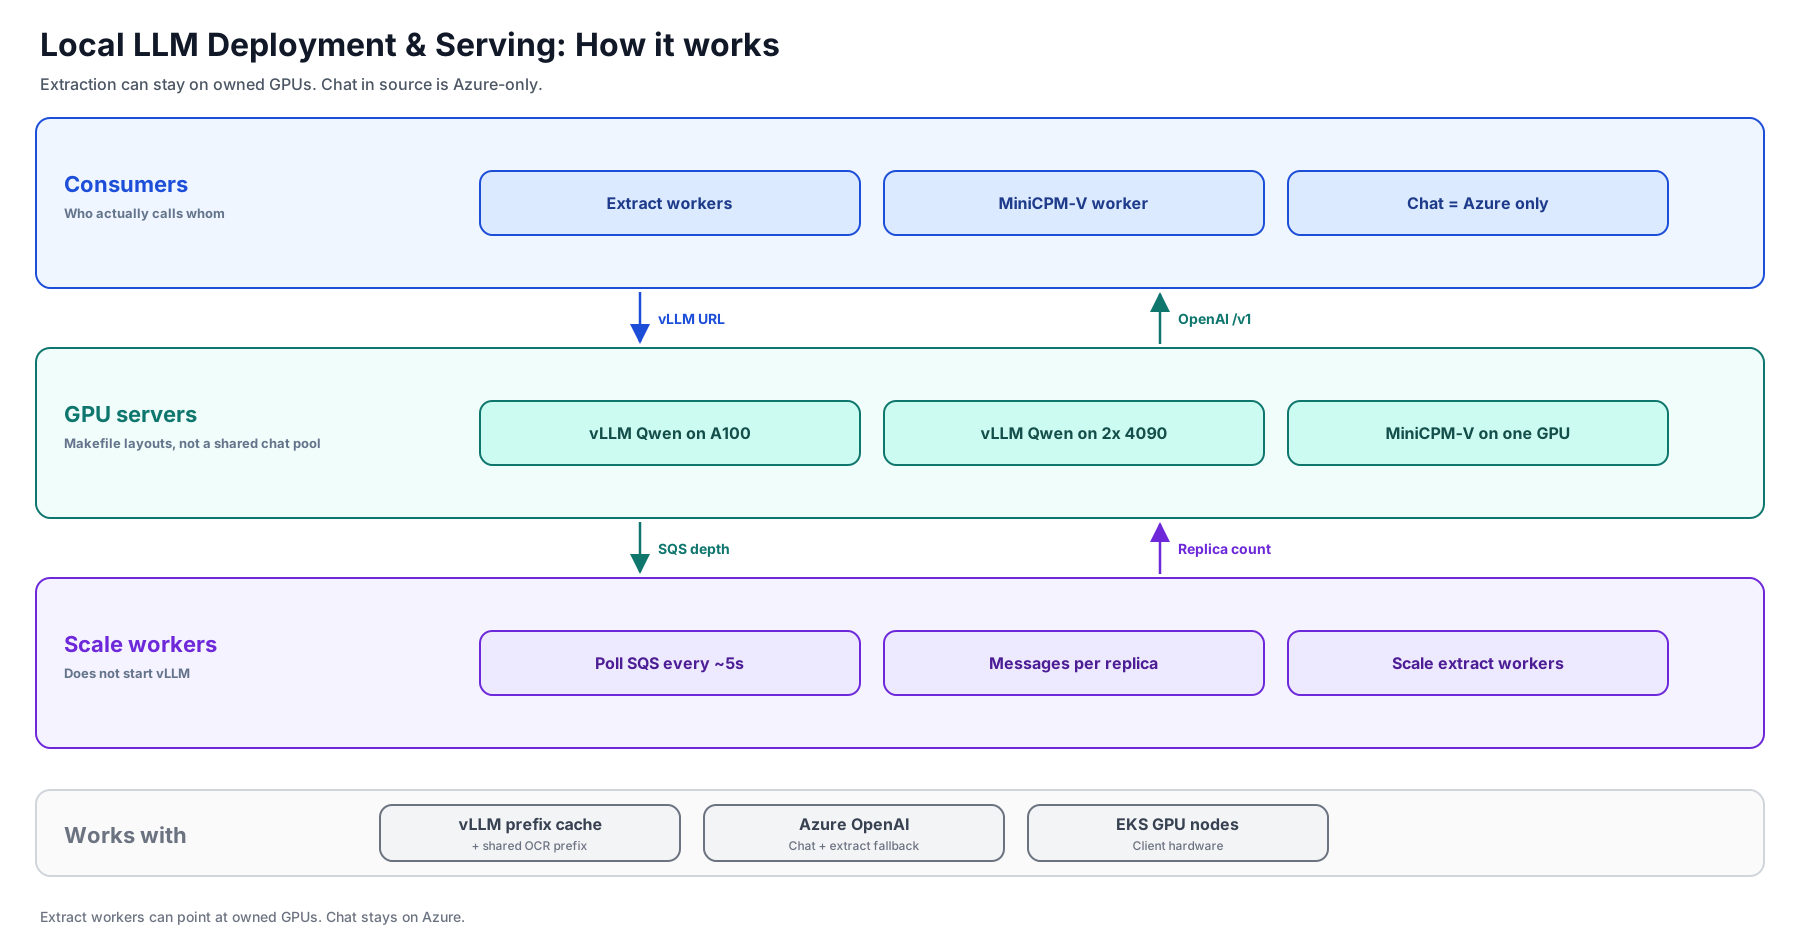
Two servers, not one “LLM box”: a MiniCPM-V form-reader worker, and vLLM serving Qwen over an OpenAI-compatible HTTP API, with prefix caching and chunked prefill. Layouts cover an A100 and a 4090 pair.
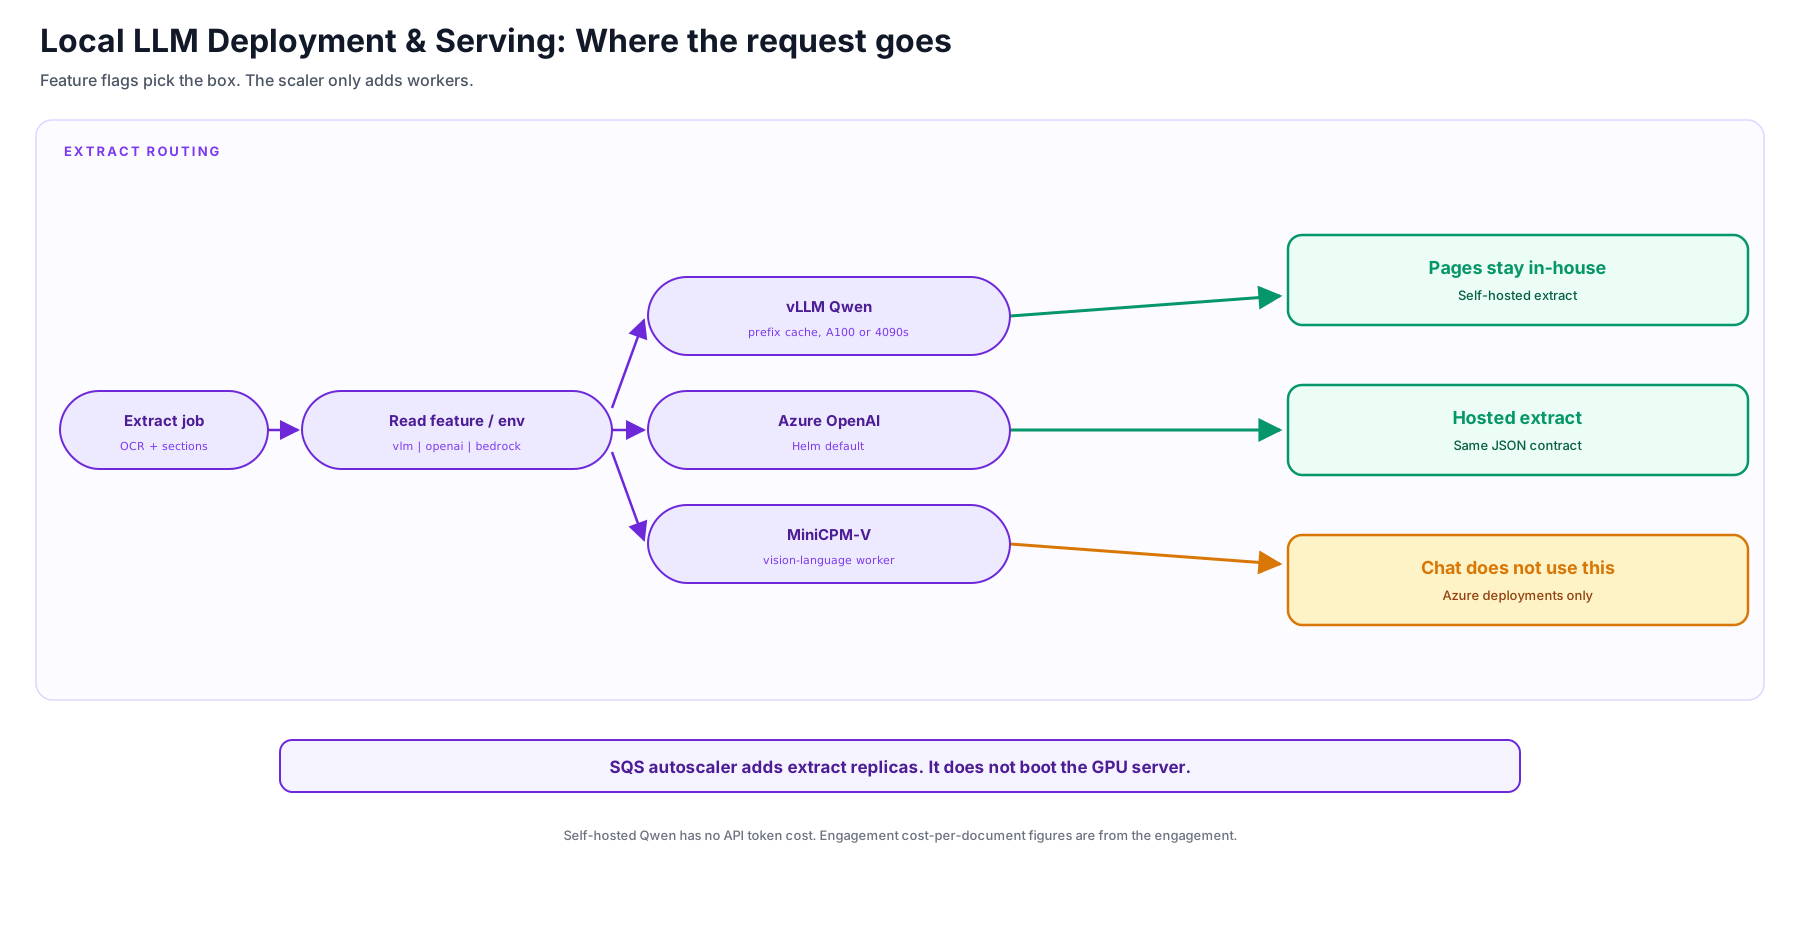
Extraction workers point at this URL when the feature flag says so. The underwriter chat API is Azure-only; it does not call this serving URL. An autoscaler samples queue depth every few seconds and changes extract-worker replicas; it does not boot the GPU server.
Outcomes
Extraction can stay on owned GPUs; chat remains on Azure.
Engagement-reported inference cost per document dropped from ~$0.35 to ~$0.10; sensitive pages no longer have to ride a public API.
How it works
Where the request goes
What we built
Serving layer
vLLM for Qwen
OpenAI-compatible HTTP, prefix cache, chunked prefill. A100 or tensor-parallel 4090s.
MiniCPM-V worker
Image plus OCR JSON into a multimodal extract, with a hosted fallback.
Queue-aware scale
Extract workers scale on queue depth. The scaler does not start vLLM.
Who consumes it
Extraction only. Chat does not share this pool.
How it works
There is no chat UI here. Feature flags pick Azure, vLLM Qwen, or MiniCPM-V for extract. Chat always Azure.
Shared OCR-and-instructions prefixes per page so section calls hit the vLLM prefix cache.
Integrations
vLLM
Prefix cache and chunked prefill on owned GPUs.
Medical extraction
Extract workers call this URL. The chat product does not.
Azure OpenAI
Extract fallback and all chat completion.
Have a similar challenge?
Start a project